A safety label is not the same as reliable understanding
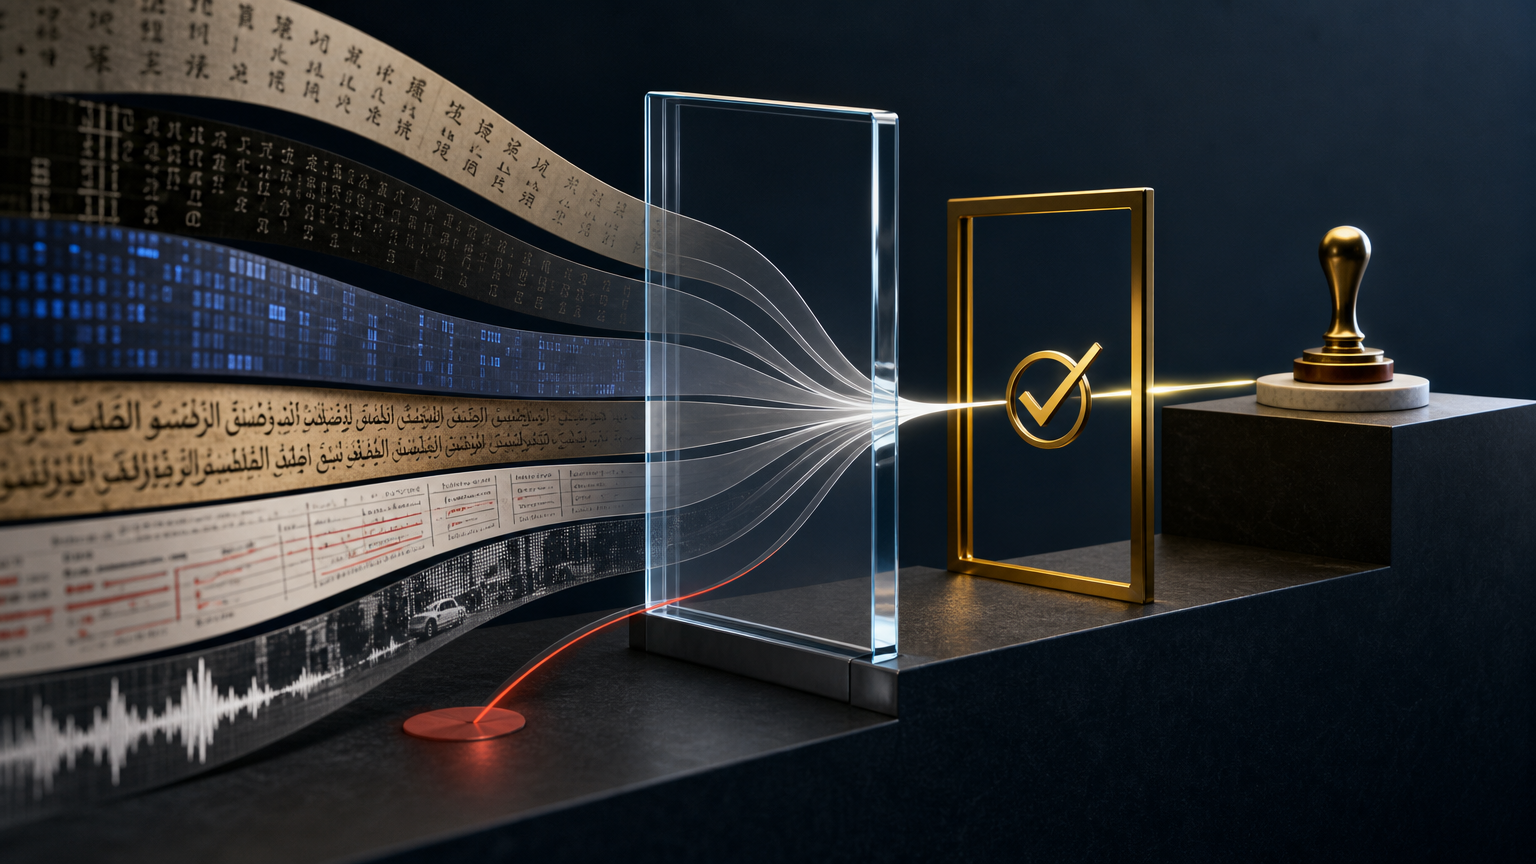
AI controls often produce concise outputs: allowed, blocked, safe, risky, or escalate. Those labels can be useful in an operating workflow. But they do not by themselves answer a prior question: did the system interpret the input reliably enough to support the action that follows?
That distinction matters when an input is ambiguous, transformed, partly translated, poorly transcribed, formatted unusually, or otherwise outside a workflow’s familiar operating range. The issue is not that unfamiliar language or presentation makes a user suspicious. It does not. The issue is whether the organization has enough evidence to give an automated system authority in that situation.
This is a governance question, not a claim that a particular model, language, or safety tool will fail. The practical task is to design for uncertainty in consequential AI workflows.
Treat interpretation confidence and policy confidence separately
A workflow may reach a policy outcome without strong evidence that the input was interpreted as intended. For example, an automated system might classify a request as permitted while a translation, normalization step, or routing rule has materially changed its apparent meaning.
It can be useful to distinguish two questions:
- Interpretation confidence: How well supported is the system’s understanding of the input, context, and requested action?
- Policy confidence: Given that interpretation, how clear is the applicable policy outcome?
Keeping these questions separate prevents an ambiguous input from being treated as confidently approved simply because a downstream classifier returned a low-risk label.
For a particular workflow, teams might define states such as:
- Interpreted with sufficient confidence; action appears permitted. The input falls within the workflow’s evaluated conditions and no restriction is identified.
- Interpreted with sufficient confidence; action is restricted. The request is clear enough to route to a refusal, limitation, or approval process.
- Interpretation is insufficient for the requested action. The workflow lacks a dependable basis for giving the system the same authority it would have with a clearer input.
These are operating considerations, not universal categories. The right thresholds depend on the action at stake and the organization’s own policies.
Identify where interpretation can change
A model is only one part of an AI-enabled workflow. An input may be identified, translated, normalized, summarized, classified, routed, logged, and converted into an action. Each stage can affect what later controls see.
A focused review can map the path from input to consequence by asking:
- Where is text, speech, or an image converted into another representation?
- Which component decides what the request means?
- Which component applies policy?
- What evidence is retained when the workflow reaches a decision?
- Can a reviewer determine why a request was interpreted and routed in a particular way?
- Which action can occur if the interpretation is incomplete or contested?
This review should include ordinary user inputs as well as inputs that present greater interpretation uncertainty. Relevant test dimensions may include language, script, dialect, code-switching, formatting, transcription quality, ambiguity, and transformations introduced by the workflow itself.
The objective is not to label those dimensions as threats. It is to understand whether the control path behaves consistently and whether uncertainty reaches the right decision point.
Test the workflow, not just a single model
A model evaluation can be useful, but it may not show how the complete process behaves. A sound-looking classification result can still be paired with a weak translation, an unexpected routing rule, missing context, or an automated action that exceeds the available evidence.
For a chosen workflow, an organization can examine questions such as:
- Do different components materially disagree about what an input means?
- Does a transformation change the apparent intent or policy outcome?
- Are low-confidence interpretations routed toward higher-impact actions?
- Does the recorded evidence allow a reviewer to reconstruct the decision?
- Does the workflow respond differently to equivalent inputs because of avoidable representation differences?
These questions do not require a claim that every hard-to-read input creates a security problem. They are a way to locate where a system’s authority may be greater than its interpretation evidence supports.
Make escalation a defined operational path
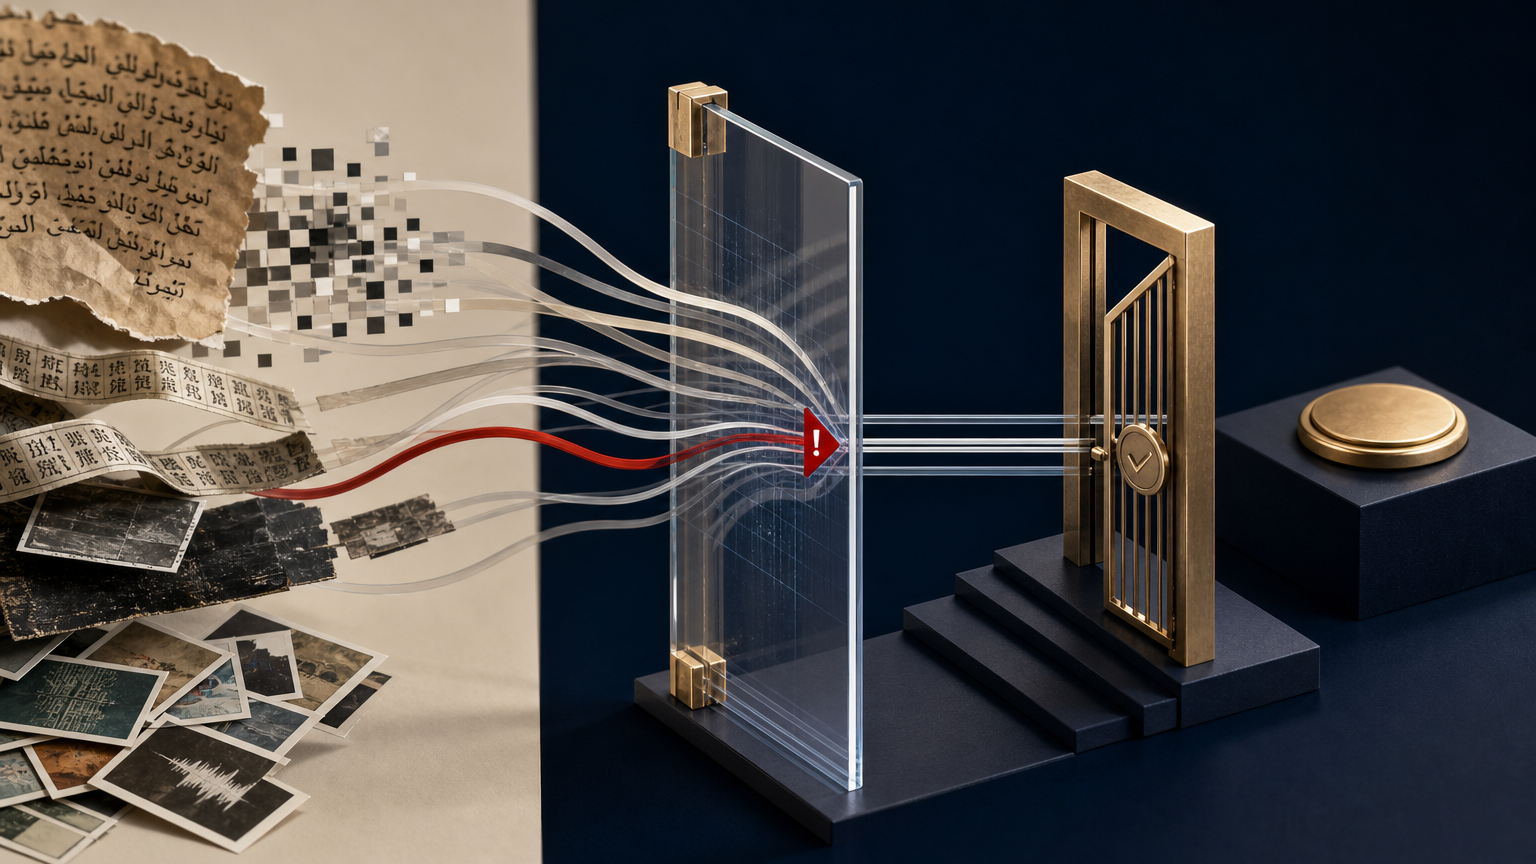
“Human review” is not, by itself, a complete control. A usable escalation path has a defined trigger, an owner, a record of the uncertainty, and an action that can be taken while the matter is unresolved.
For higher-impact workflows, organizations may choose to consider escalation when there is unresolved disagreement among checks, unclear interpretation of the requested action, missing context, or an attempt to affect access, sensitive information, funds, or durable system state. The response can be proportionate to the risk. Depending on the workflow, it may involve asking for clarification, narrowing the response, delaying execution, requiring authorization, or declining to take an automated action.
The important design principle is simple: unresolved uncertainty should change what the system is allowed to do. It should not disappear because a workflow requires a quick answer.
Keep consequential authority outside a language-only decision
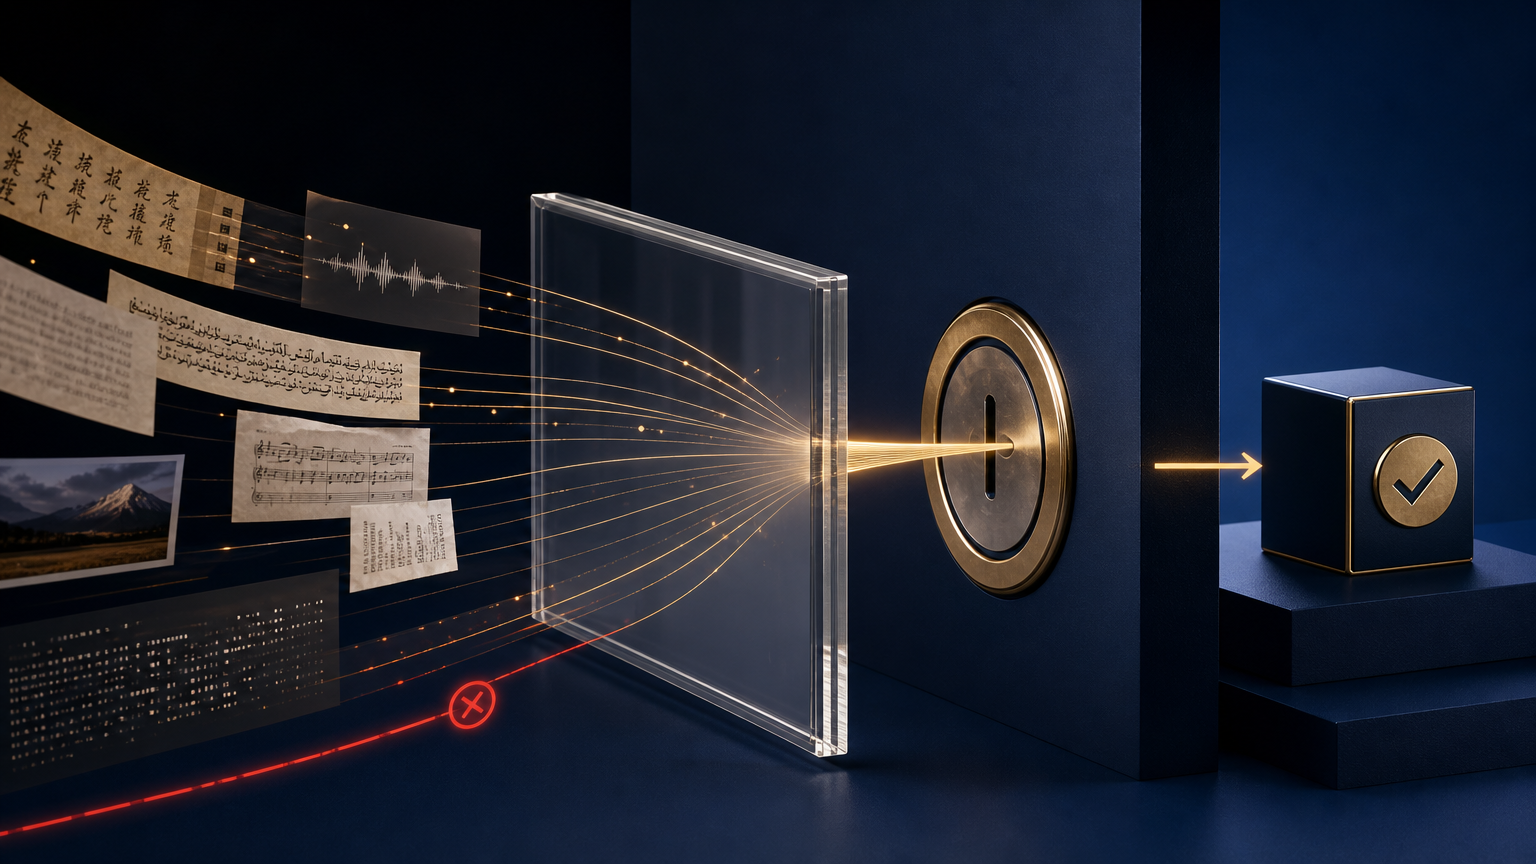
Language-based screening, classification, and review can be valuable inputs to a decision. They are more resilient when they are not the only constraint on a consequential action.
Depending on the use case, independent safeguards may include:
- narrowly scoped permissions;
- separation between analysis and execution;
- approval requirements for durable changes;
- limits on access to sensitive data;
- validation before a transaction or external action;
- limits on the size or scope of an automated action; and
- audit records that preserve the basis for a decision.
These measures are not a one-size-fits-all checklist. They are examples of controls that can limit consequences even when an AI system’s interpretation is uncertain. A permission boundary, approval step, or transaction limit can provide a distinct basis for control rather than relying only on a language-derived safety judgment.
Preserve access and accountability
A cautious approach should not turn linguistic unfamiliarity into a proxy for harmful intent. Legitimate users may communicate through a wide range of languages, scripts, accessibility tools, speech transcription, translation tools, or domain-specific terminology.
That creates two responsibilities. First, teams should avoid treating uncertainty as an automatic accusation. Second, they should examine whether some users encounter more friction, delay, or denial because a workflow has limited evaluation coverage.
Meaningful review requires enough context to challenge an automated conclusion. Reviewers should be able to see the requested action, the interpretation reached by the workflow, the uncertainty detected, and the authority boundary that applies. They should also have the ability to disagree with the system’s interpretation.
A practical starting point
Choose one AI-supported workflow where an incorrect action would have meaningful consequences. Map the points where an input is interpreted or transformed. Document the authority granted at each point. Then decide what should happen when interpretation confidence is insufficient for that authority.
The result does not need to be an elaborate program. It can begin with a clear rule for a single workflow: uncertainty routes to clarification, limited output, approval, or no automated action.
The central lesson is not that language-based controls have no value. It is that a safety label should be understood in context. Where interpretation is difficult and consequences are significant, organizations can strengthen governance by making uncertainty visible, routing it deliberately, and maintaining controls that do not rely solely on a system’s interpretation of language.